Anthropic's Claude Fable 5.2 Tops Intelligence Index at Lower Price
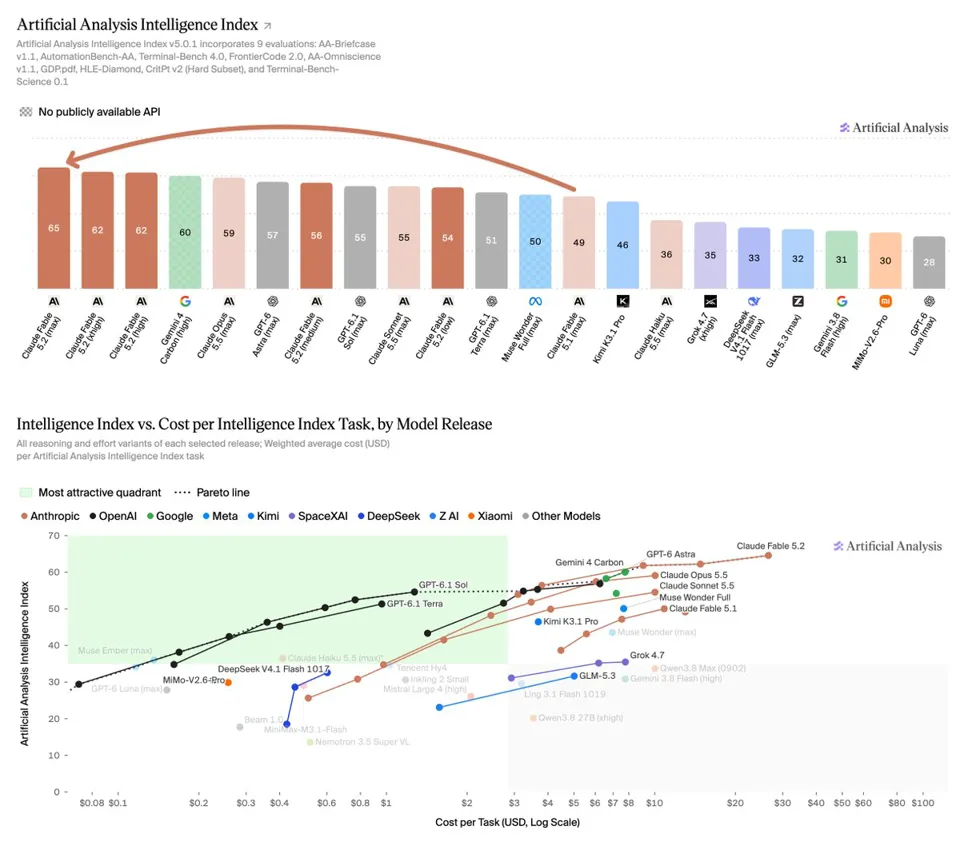
Anthropic released Claude Fable 5.2, which takes the top spot on the Artificial Analysis Intelligence Index v5 at 65, five points ahead of Gemini 4 Carbon and six ahead of Claude Opus 5.5, driven by gains in scientific reasoning, knowledge and FrontierCode 2.0 coding. Pricing drops 20% versus Fable 5.1 to $8/$40 per 1M input/output tokens, though max-effort cost per task of about $26.5 remains far above Opus 5.5.
Related Entities
Full Report
Artificial Analysis (@ArtificialAnlys) · 2026-11-09 19
Anthropic has released Claude Fable 5.2, taking the #1 spot on the Artificial Analysis Intelligence Index v5 at 65, led by gains in science, knowledge, and coding
At max effort it scores 65, 5 points ahead of Gemini 4 Carbon (high, 60) and 6 ahead of Claude Opus 5.5 (max, 59). Gains are driven by scientific reasoning, knowledge and FrontierCode 2.0, and roughly matching Opus 5.5 on AA-Briefcase and Terminal-Bench 4.0.
Priced at 40 per 1M input/output tokens, a 20% reduction from Fable 5.1, Claude Fable 5.2 averages a Cost per Task of 10.0) and ~2x compared to Fable 5.1 (max, $12.99)
Key takeaways:
➤ Claude Fable 5.2 leads 5 of the 9 evaluations in the Intelligence Index: At max effort, Fable 5.2 scores 65, ahead of Gemini 4 Carbon (high, 60), Claude Opus 5.5 (max, 59) and GPT-6 Astra (max, 57), and ~15 points above Claude Fable 5.1 (max, 49). It sets the highest scores on HLE-Diamond (80%, previous best 69% from Gemini 4 Carbon), AA-Omniscience v1.1 (67, previous best 54 from Gemini 4 Carbon), Terminal-Bench-Science (73%, previous best 65% from Gemini 4 Carbon), CritPt v2 hard subset (77%, previous best 72% from GPT-6 Astra) and FrontierCode 2.0 (49%, previous best 46% from Claude Opus 5.5)
➤ Less progress in agentic knowledge work and terminal coding: Claude Fable 5.2 improves on Fable 5.1 across capabilities, but sometimes only to Opus 5.5 levels. It reaches 1785 Elo on AA-Briefcase, within the confidence interval of Opus 5.5 (1800) and just behind Claude Sonnet 5.5 (1813). On GDP.pdf it reaches 24% all-pass against 26% for Opus 5.5. On Terminal-Bench 4.0 it scores 60%, level with Opus 5.5 and behind Kimi K3.1 Pro (67%), Gemini 4 Carbon (65%) and Sonnet 5.5 (64%). AutomationBench-AA is an exception, at 76% against 70% for Opus 5.5, narrowly behind Gemini 4 Carbon, 78%
➤ Lower efforts still take leading positions: With high and xhigh effort, Claude Fable 5.2 scores 62, ahead of every other model at any effort, using 98k output tokens per task against 173k for Opus 5.5 (max). At max effort Fable 5.2 costs ~2.6x more than Opus 5.5, but at lower effort settings it can outperform Opus 5.5 at lower cost per task
Other model details:
➤ Context window: 1 million tokens with image and text input
➤ Pricing: 40 per 1M input/output tokens; cache writes 16 with 1-hour TTL, and cache reads $0.20
➤ Effort settings: five (low, medium, high, xhigh, max). Intelligence Index evaluations were run at all five with Anthropic's default fallback enabled
Congratulations to @AnthropicAI on this impressive release!