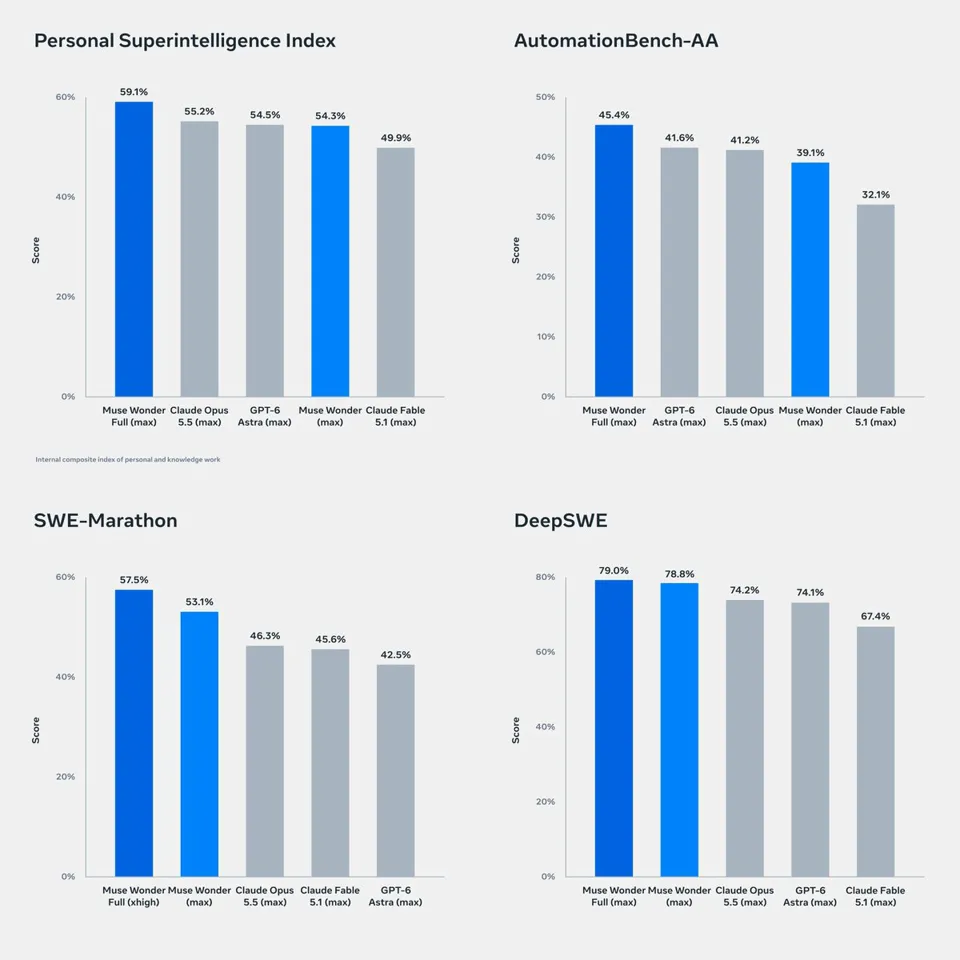
Meta Launches Muse Wonder: Beats Claude Opus 5.5 and GPT-6 Astra on SWE-Marathon Benchmark with 57.5 Score
Meta has officially released its new frontier model, Muse Wonder, claiming state-of-the-art performance in personal and professional agent tasks. The model scored 57.5 on the SWE-Marathon benchmark, significantly outperforming Anthropic's Claude Opus 5.5 (46.3) and OpenAI's GPT-6 Astra. This result signals Meta's return to technical leadership in complex software engineering agents.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-10-12 18
Meta is so back. in each of these benchmarks Muse Wonder beats both Opus 5.5 and GPT-6 Astra
The widest gap comes on SWE-Marathon. this one tests whether an AI agent can build an entire software project on its own, such as a C compiler or a Slack clone, over 2 to 10 hours, and counts a task only if every hidden check passes.
And muse wonder full scores 57.5 against 46.3 for Opus 5.5.
↳ 引用 @alexandr_wang (Alexandr Wang): introducing muse wonder
our new frontier model. state-of-the-art at personal agents and professional agents.
our largest and most capable model yet—rivals the big bois