Meta Launches Muse Wonder: Beats Claude Opus 5.5 on Long-Horizon Agentic Benchmarks
Meta has released the Muse Wonder family of frontier models, with its top version outperforming Claude Opus 5.5 on 8 of 14 benchmarks. The model demonstrates significant advantages in long-horizon coding and legal automation, notably scoring 57.5 vs. 46.3 on SWE-Marathon, signaling Meta's return to the AI frontier.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-10-12 17
Muse wonder brings Meta back to the frontier of AI
They just released Muse Wonder, whose top version beats Claude Opus 5.5 on 8 of 14 published benchmarks.
A rally major milestone for Zuckerberg
Its ahead of GPT-6 Astra and Claude Fable 5.1 on long-running coding, legal work and business automation.
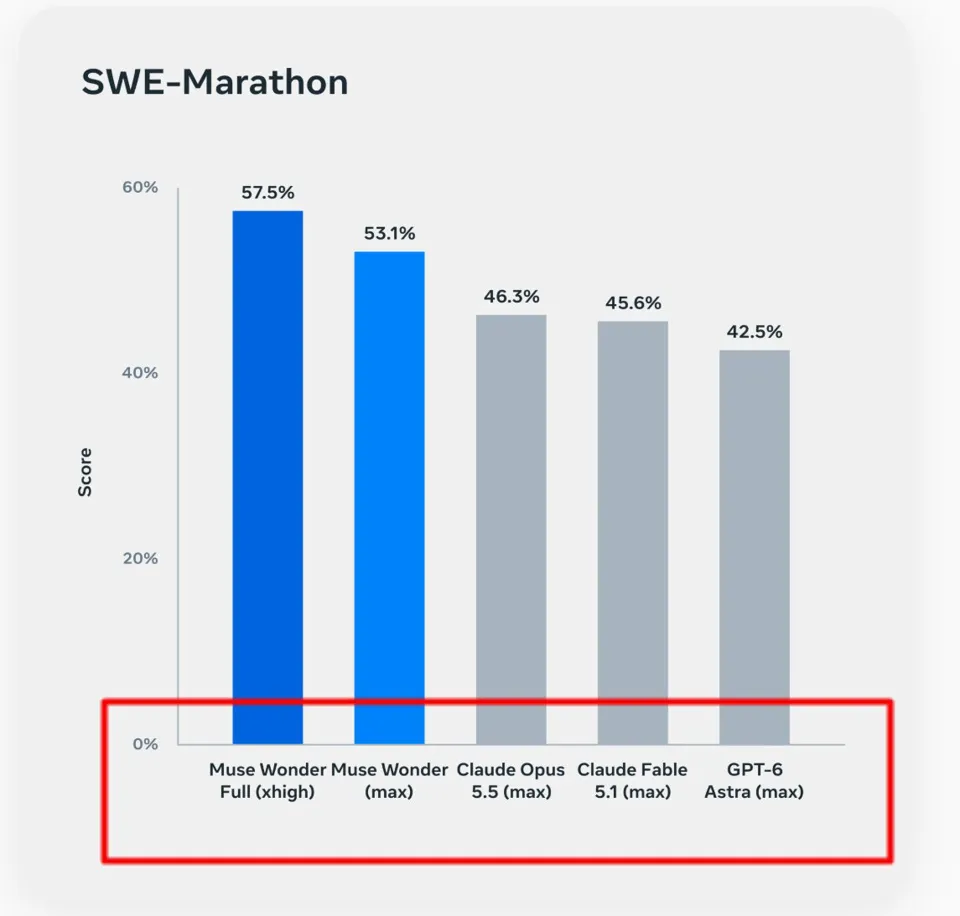
The widest gap comes on SWE-Marathon, an ultra-long engineering test, where Full scores 57.5 against 46.3 for Opus 5.5.
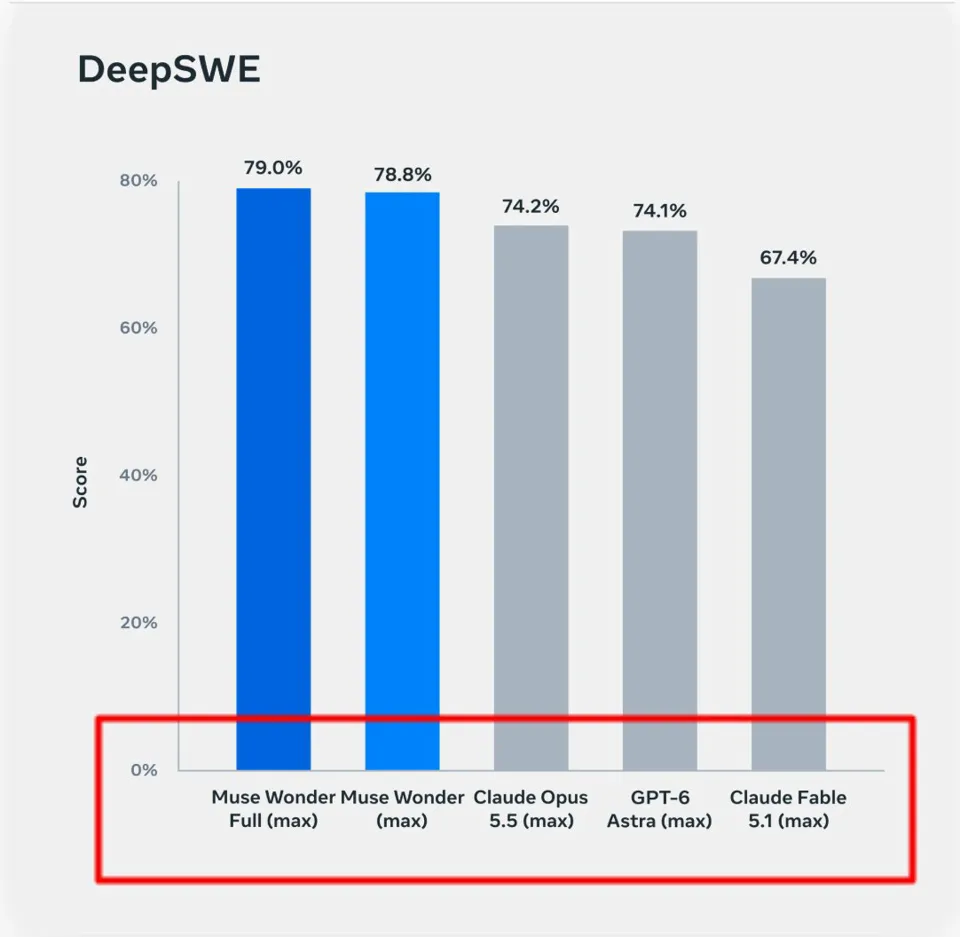
Full also leads DeepSWE 1.1, a long-horizon coding test, 79.0 to 74.2, in what Meta says were independent third-party runs.
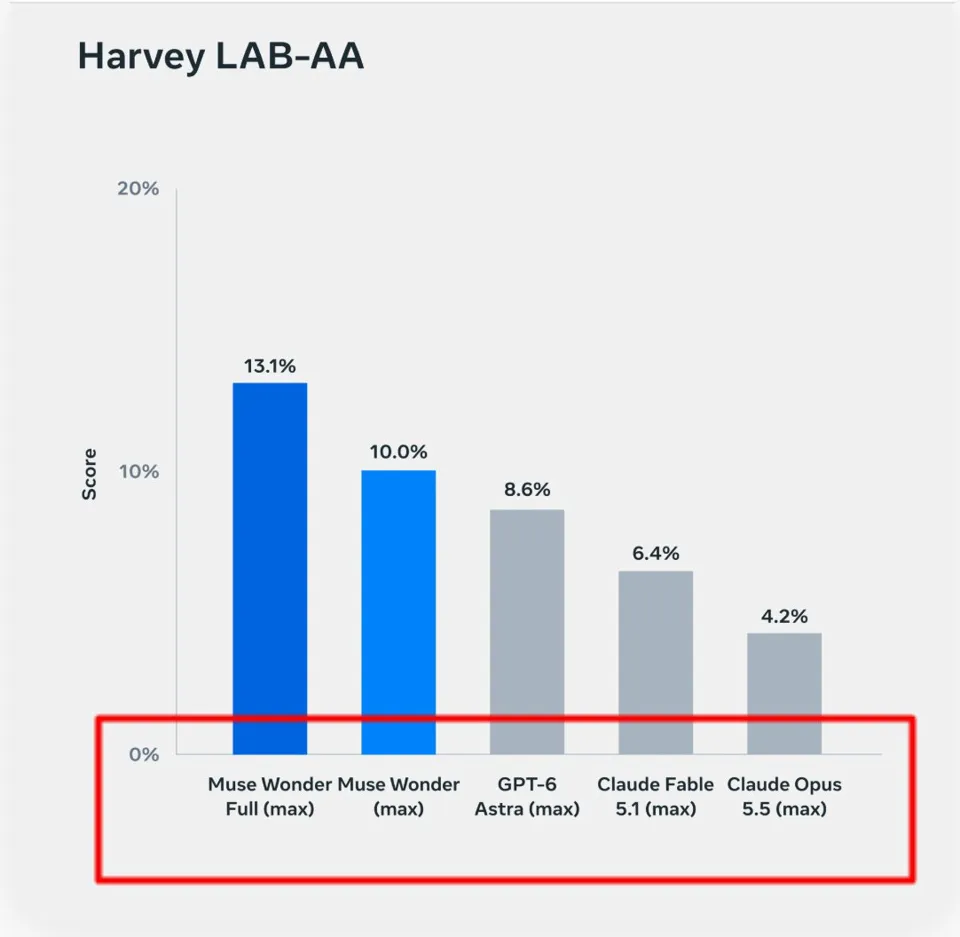
On Harvey’s legal agent benchmark, which credits only tasks finished in full without hallucination, Full scores 13.1, more than triple Opus 5.5’s 4.2.
↳ 引用 @finkd (Mark Zuckerberg): Introducing Muse Wonder, our new family of frontier models with state of the art performance for personal and professional agentic work.