Moonshot AI Releases Kimi K3.1 Pro, Outperforming GPT-6 in Coding Benchmarks
Moonshot AI has officially launched the 3-trillion parameter Kimi K3.1 Pro, which surpasses GPT-6 in coding agent benchmarks like Terminal-Bench. The model features advanced 3D spatial reasoning and parametric modeling capabilities, allowing it to directly generate scripts for tools like CAD and Blender. A high-speed version is also available to reduce latency, with full weights scheduled for open-source release in early November.
Full Report
The high-speed model, Kimi K3.1 Pro Highspeed, is now available simultaneously, offering equivalent intelligence with output speeds approximately 2–3 times faster.
Effective immediately, users can access the Kimi K3.1 Pro and Kimi K3.1 Pro Highspeed models via kimi.com, the Kimi App, Kimi Work, Kimi Code, and the Kimi API (platform.kimi.com). Full model weights will be released by November 4.
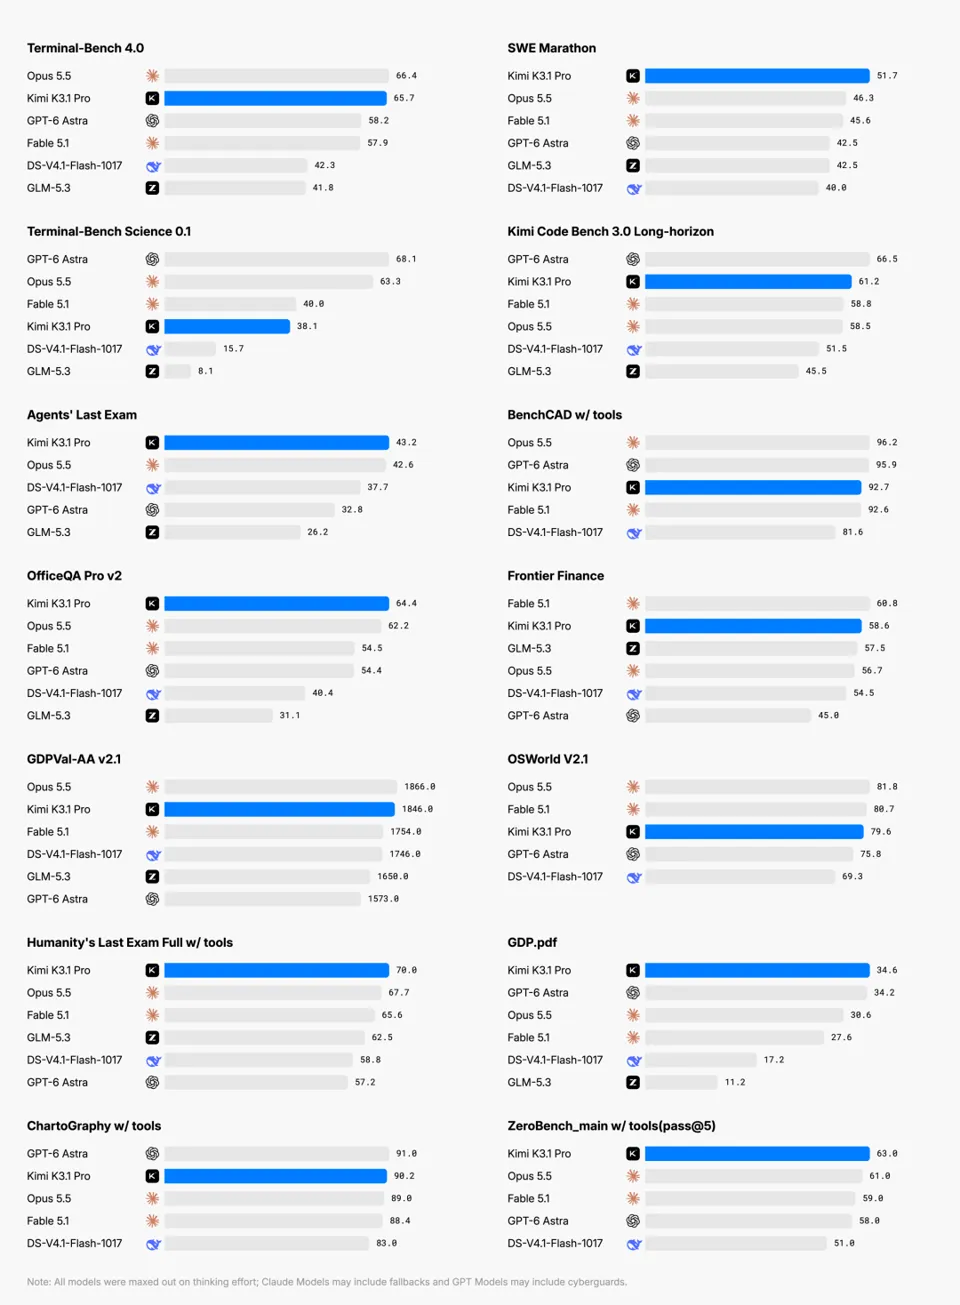
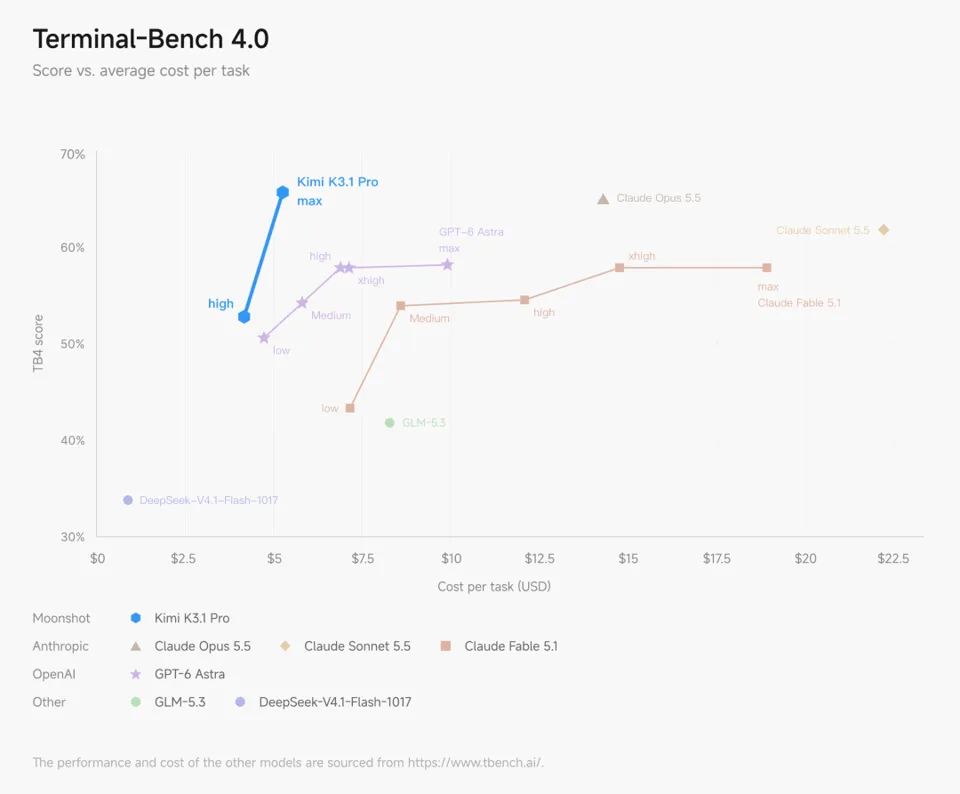
According to official information obtained by IT Home, on coding, agent, and knowledge benchmarks, K3.1 Pro matches or approaches the performance of the strongest closed-source models. Terminal-Bench 4.0 evaluates programming agents' capabilities through resource-constrained terminal tasks in real-world environments, with each task featuring rigorous specialized tests. K3.1 Pro scored 65.7% in this evaluation, surpassing GPT-6 Astra (58.2%) and trailing only slightly behind Claude Opus 5.5 (66.4%).
Kimi Code Bench 3.0 Long-horizon is an internal benchmark covering various engineering domains, focusing on programming agents' multi-step execution, tool calling, and end-to-end problem-solving abilities. K3.1 Pro scored 61.2% in this test, higher than K3's 55.95%.
K3.1 Pro demonstrates proficiency in using game engines such as Unity, Unreal Engine, and Godot, combining web search with 3D generation to create complete experiences. Its generated frontend pages, Three.js interactive scenes, and 3D assets show significant improvements in composition, layout, animation, and detail refinement.
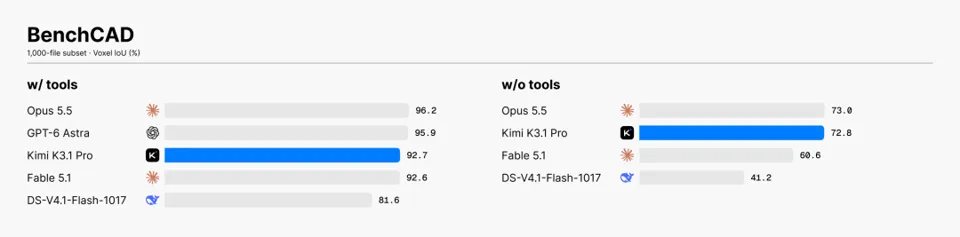
The Kimi K3.1 Pro model excels in 3D creation and spatial reasoning. In the BenchCAD benchmark, K3.1 Pro achieved a score of 92.7% with tool assistance, approaching Claude Opus 5.5's 96.2% and GPT-6 Astra's 95.9%. This benchmark assesses the ability to reconstruct 3D models from multi-view renderings by generating CAD code.
According to reports, given a text description, a sketch, or a reference image, K3.1 Pro can infer object shapes, proportions, and spatial relationships and reconstruct them into usable 3D models. It also has a stronger understanding of existing asset and model libraries.
K3.1 Pro specializes in parametric modeling, such as mechanical parts, architectural models, multi-parameter configurable products, and custom furniture. Without relying on MCP connectors, it can directly write and run scripts for professional modeling tools like Blender and CAD, completing asset construction and refinement, modifying individual components, and adjusting geometry, materials, and scene layouts.
The 3D Make feature is now live on kimi.com and the Kimi app, supporting online preview and editing of 3D models. Finished models can be downloaded directly for 3D printing, or exported as videos or Live Photos for easy sharing on social platforms.
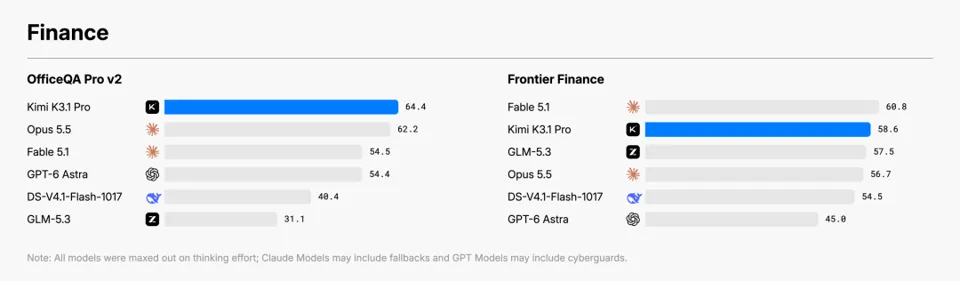
Kimi K3.1 Pro is also capable of delivering complete financial workflows end-to-end. On external benchmarks, K3.1 Pro scored 64.4 on the OfficeQA Pro v2 benchmark, achieving the current State-of-the-Art (SoTA). OfficeQA Pro v2 evaluates complex financial data analysis based on real-world financial documents, involving retrieval, cross-document verification, and multi-step numerical reasoning.
K3.1 Pro's performance on Frontier Finance has further improved over K3. This benchmark measures the model's support for complete investment workflows, covering the entire process from target screening to profitability analysis.
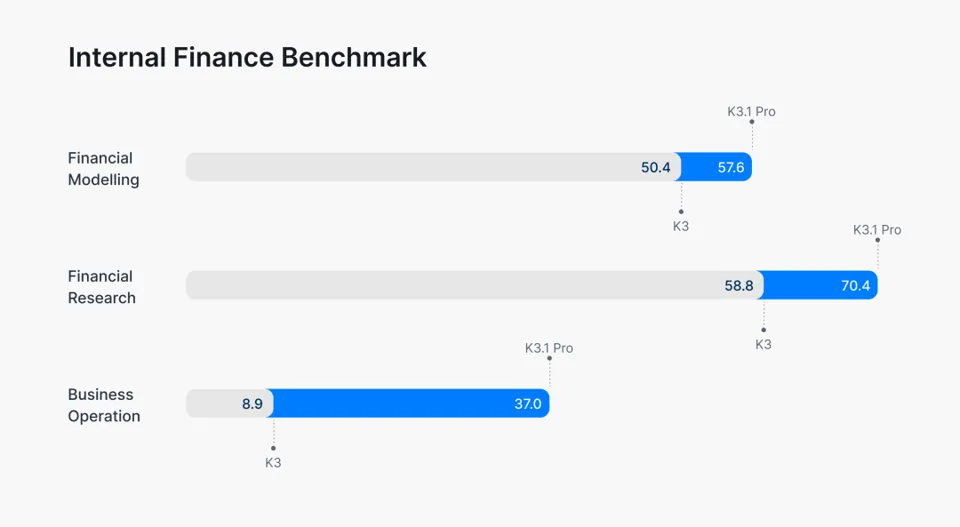
On three internal financial benchmarks, K3.1 Pro comprehensively outperforms K3:
- The Financial Modelling benchmark evaluates formula linkage, financial logic, and final workbook quality in real modeling tasks; K3.1 Pro improved by 14% over K3.
- The Financial Research benchmark tests whether the model can perform real-world financial research tasks and output verifiable results under evidence and deadline constraints; K3.1 Pro improved by 20% over K3.
- The Business Operation benchmark assesses long-term management and decision-making capabilities in simulated business environments; K3.1 Pro's score is approximately 4.2 times that of K3.
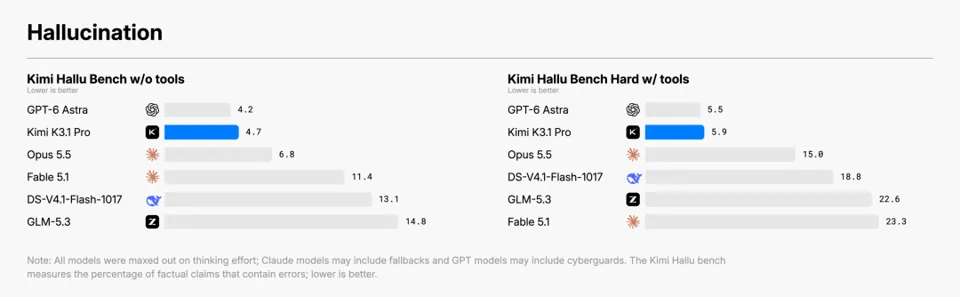
In Kimi Hallu Bench Hard, an internal stress test specifically targeting factual accuracy, the new model reduced its single-fact statement error rate from 23.4% (in K3) to 8.3%; the proportion of responses containing at least one factual error is only about 42.4% of the previous generation. (Note: This is a stress test for factual accuracy where samples deliberately focus on scenarios where models are prone to errors; the reported error rates do not represent overall performance in daily use.)
To integrate Kimi API into your applications: Visit the Kimi Open Platform (platform.kimi.com), select the kimi-k3.1-pro model. Pricing is ¥1.3 per million input tokens (cache hit) and ¥13 per million input tokens (cache miss), with output priced at ¥68 per million tokens. For the high-speed model kimi-k3.1-pro-highspeed, which offers approximately 2–3x faster output speed, pricing is doubled.