Joy Dataset Released with 100k Hours of Real Voice Conversations
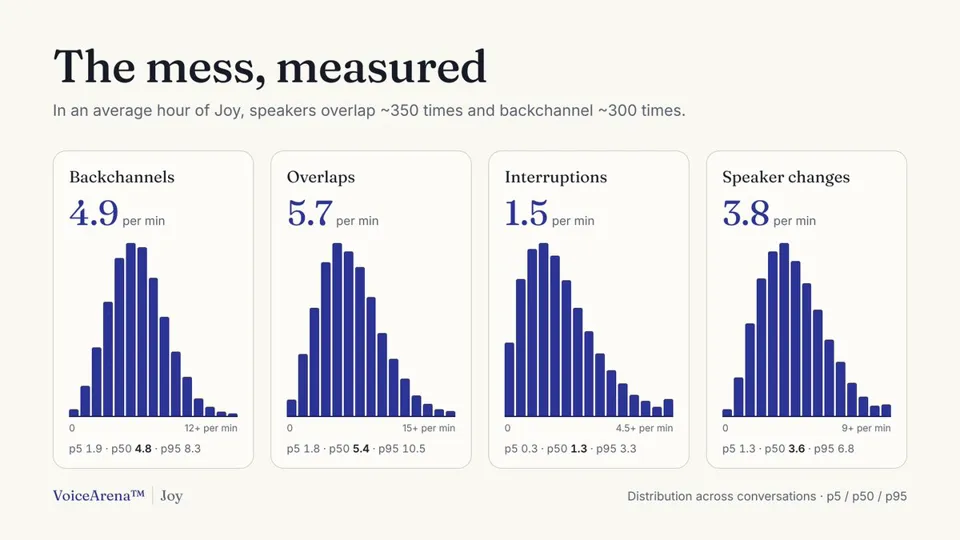
The open-source community released the Joy dataset, featuring 100,000 hours of dual-channel, unscripted real conversations across 50,000 speakers and 10 languages. This data addresses the rigidity of current voice AI trained on synthetic dialogue by providing authentic signals for interruptions, overlaps, and natural pauses, enhancing models' understanding of complex human conversational rhythms.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-10-29 18
Unscripted calls are hard to collect at scale. Voice AI today mostly learns from fake dialogue written by LLMs and read aloud by TTS, so it never hears people talking over each other;
Really curious how they kept the conversations going for 10 to 20 minutes.
They released Joy, a 100,000 hours of unscripted, two-person conversation across 10 languages
↳ 引用 @shobhitbanga (Shobhit Banga): Drop 1/15: Introducing Joy, a dual-channel conversational dataset. Real, unscripted conversations between two people, each on their own track. Built to teach voice models how people actually talk: when to listen, when to jump in, when to say “hmm”.
100,000 hours. 50,000 speakers. 10 languages.